Skip to content

AI/ML EngineeringAgentic AI development, built and tested for a specific task.

We build chatbots, voice agents and workflows on your data, tested against real examples. Discovery first decides whether AI fits the task.

Packages

Start with a package

Four packages, each with its price on the page. Pick one and buy it online.

Billing

What you get

What you walk away with.

  1. Labeled evaluation set owned by your experts
  2. Accuracy, latency and cost against a baseline
  3. Human review interface that captures corrections
  4. Vendor-agnostic model layer with a fallback
  5. Prompt-injection and data-leakage review
  6. Drift and cost monitoring with an owner

Sounds like

You might recognize one of these.

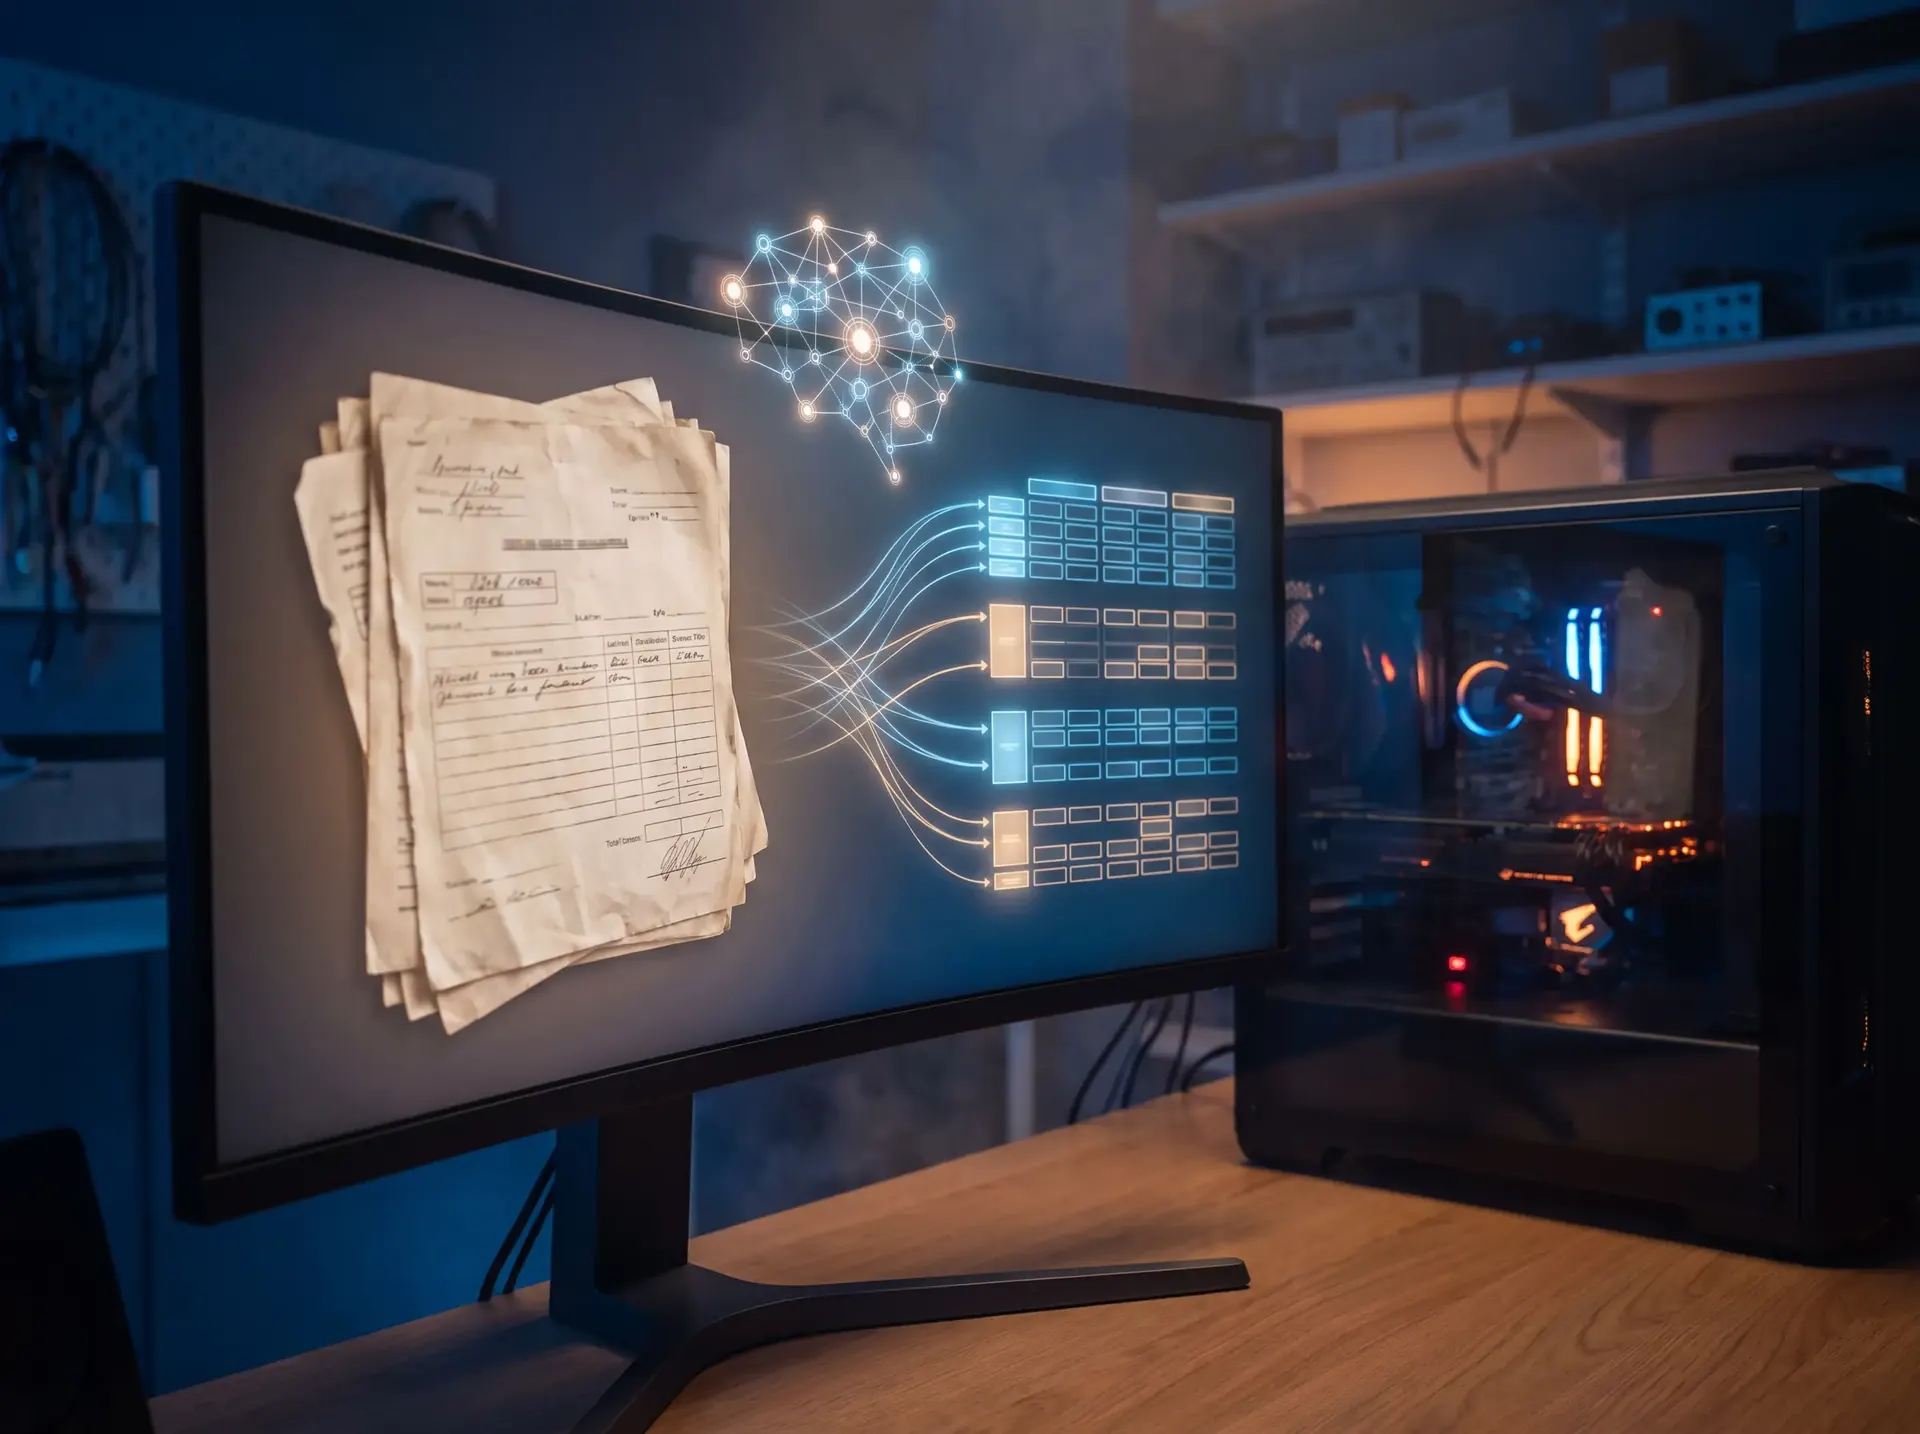
  • Four people spend their week retyping data from PDFs.

  • We tried a chatbot and it confidently made things up.

  • Our forecast is a spreadsheet someone maintains by hand.

  • The board wants an AI strategy and we need it to be real.

How it runs

Phases and timing.

  1. 2–3 weeks

    AI feasibility sprint

    Fixed fee. We take one candidate use case, build an evaluation set and prove or disprove it on your real data. It ends in a straight answer on whether the use case is worth building, with the evidence attached.

  2. 6–12 weeks

    Production pilot

    One workflow, one team, in production behind a review queue, with the accuracy and savings measured rather than asserted.

  3. Ongoing

    Scale-out

    Additional use cases on shared evaluation, observability and governance infrastructure.

The detail

What the scope includes.

AI/ML Engineering

We build AI tools for a defined task using your business information. Options include fine-tuning, document search, chatbots, voice agents and automated workflows. We evaluate a simpler approach before recommending model training.

More about AI/ML Engineering

You decide which steps run unattended and which wait for a person to approve them. Every action is logged, so you can see what was done and when.

Fine-tuning
Training an existing model on your examples and measuring its performance on the intended task
Chatbots
Answering questions from your documents, policies and data, on your site, in your internal tools or in Teams and Slack, handing the conversation to a person when it cannot answer
Voice agents
Answering and making calls in natural speech, booking appointments, taking messages and routing callers, with anything that needs a person going to your staff
Agentic workflows
Carrying out multistep tasks across your tools, such as processing incoming documents, updating records or drafting replies

When this service fits

  • You want help answering and routing inbound calls
  • You want to search your SOPs and documents with AI
  • You want a custom AI that runs inside a highly regulated environment
  • You want a model adapted to your business terminology and tasks
  • You want to detect unusual activity, such as fraud
Show all 5 parts of the scope
  • Document intelligence

    Extraction from invoices, claims, purchase orders and scanned contracts, with confidence thresholds that send uncertain cases to a person.

  • Retrieval-augmented assistants

    Answers grounded in your own documents, with citations, refusal when the source is silent, and access control enforced at retrieval.

  • Classification, routing and prioritization

    Triage of tickets, claims, leads and exceptions behind a queue, reviewed by a person until the model earns autonomy.

  • Forecasting and optimization

    Demand, capacity, maintenance and route optimization, evaluated against the naive baseline, which a surprising number of models lose to.

  • Evaluation and guardrails

    Every model ships with a labeled evaluation set, tracked accuracy and cost, prompt-injection defenses, output validation and a fallback for provider outages.

Show the tools we use
Models
  • Claude
  • GPT
  • Gemini
  • Llama
  • Open-weight, self-hosted
Retrieval
  • pgvector
  • Elasticsearch
  • Hybrid BM25 + dense
  • Rerankers
Classical ML
  • scikit-learn
  • XGBoost
  • PyTorch
  • Prophet
Operations
  • Evaluation harnesses
  • LangFuse
  • Cost telemetry
  • Drift monitors

Questions

Common questions.

  • Not unless you decide it should be. We deploy on enterprise terms with training explicitly disabled, or self-host open-weight models inside your own boundary when policy or classification requires it.

  • Constrain the task, ground answers in retrieved sources, validate outputs against a schema, require citations, and let the system say it doesn’t know. Then measure how often it’s wrong on a fixed evaluation set, because unmeasured accuracy is just a feeling.

  • We instrument cost per task from day one and design for it: smaller models where they suffice, caching, batching. Unit economics is a design constraint in these projects, not a surprise at the end of the month.

The other practices

Where this practice stops, and who picks it up.

Software that runs a business process: the application, the data behind it, and the integrations that keep it fed.

Next step

Tell us what’s breaking.

Forty-five minutes, no charge. We’ll say what we’d do, what it would likely cost, and whether what you already have can be made to work.

Reply
A person replies, not a sequence: within one business day, from someone who would be on the engagement.